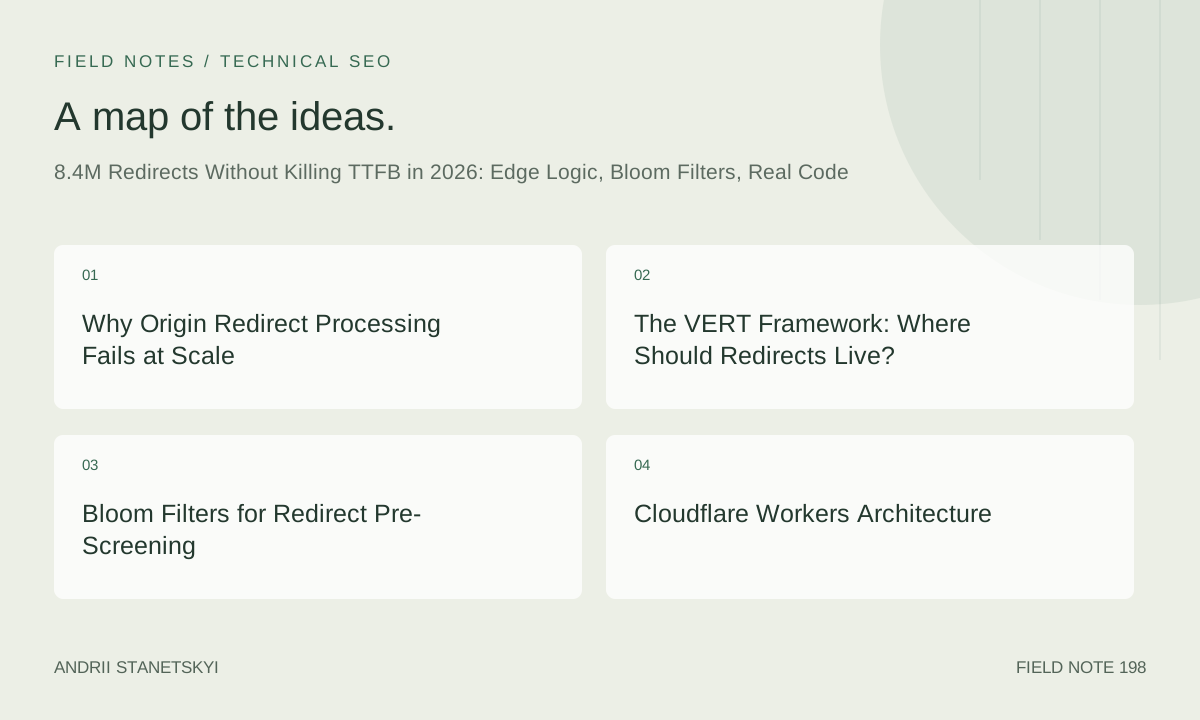
The number was 8,412,847 redirects. That's what we inherited after a platform migration for a large retail client in January 2026—eight years of URL changes, product discontinuations, category restructures, domain acquisitions, and a complete replatform from a custom monolith to a headless Shopify setup. Every one of those redirects was technically necessary. And every one of them was being processed at origin, which meant a 340ms lookup penalty on every request that hit a legacy URL.
By April 2026, we'd moved the entire redirect set to the edge. TTFB for redirected requests dropped from 340ms to under 8ms. Here's exactly how we did it.
Why Origin Redirect Processing Fails at Scale
The traditional approach to redirects is an Apache/Nginx rewrite rules file or a database lookup at origin. For sites with a few thousand redirects, this is fine. For sites with millions, it breaks in three distinct ways.
Memory pressure. An Nginx map block with 8M entries consumes north of 2GB of RAM on load. At that size, you're not serving rewrites from RAM—you're thrashing swap. The alternative, database lookups, adds a round-trip to your data store on every request that hits a legacy URL.
Deployment latency. When the redirect table changes (product discontinuations, category renames), you have to reload the configuration or update the database. At origin, that means a deployment or a database write that every server in your fleet has to reflect. At scale, you're looking at 5–15 minutes of propagation before a new redirect is active everywhere.
Geographic latency. Origin redirect processing means the request has to travel to origin before getting the 301 response. For a user in Sydney hitting a legacy URL that maps to a new URL that's served from a CDN edge node also in Sydney—the request leaves Sydney, goes to your US origin, gets a 301, comes back to Sydney to get the actual page. You've added a full transatlantic round trip to what should be a single hop.
Edge redirect processing eliminates all three. The redirect lookup happens at the PoP closest to the user, in memory, before the request ever touches origin.
The VERT Framework: Where Should Redirects Live?
Not all redirect sets belong at the edge. Some are too complex for edge logic. Some change too frequently for edge deployment cycles. The VERT framework—Volume, Edge-readiness, Rule-complexity, Temporality—helps make the placement decision.
| Dimension | Edge (CDN) | Middleware | Origin |
|---|---|---|---|
| Volume | >100K redirects | 10K–100K | <10K |
| Edge-readiness | Static URL-to-URL mappings | Pattern-based with simple params | Requires DB queries or session data |
| Rule-complexity | Exact match or simple regex | Multi-condition rules | Rules requiring business logic |
| Temporality | Stable (changes <daily) | Changes daily to weekly | Real-time changes |
For our 8.4M redirect case: volume was extreme, the rules were almost entirely exact URL-to-URL mappings (about 7.9M exact, 500K pattern-based), and the table changed weekly not in real-time. VERT score: pure edge candidate. The 500K pattern-based redirects we split out to a middleware layer on Cloudflare's own edge via a separate Worker that handled the regex evaluation.
Bloom Filters for Redirect Pre-Screening
How Bloom Filters Work
A Bloom filter is a bit array with a set of hash functions. When you add a URL to the filter, each hash function generates an index, and you set those bits to 1. When you check whether a URL is in the filter, you check all those bit positions. If any bit is 0, the URL is definitely not in the set. If all bits are 1, the URL is probably in the set—with a false positive rate you can tune by adjusting the array size and number of hash functions.
For redirect pre-screening, the false positive doesn't matter much. If the Bloom filter says "probably a redirect" for a URL that isn't actually in the redirect table, you do a full KV lookup and return a miss. Slightly wasteful but not harmful. What matters is the true negative: if the filter says "definitely not a redirect," you skip the KV lookup entirely and pass the request through to origin immediately.
For a site where 95% of requests are not redirects, this means 95% of requests skip the KV lookup entirely. Only the 5% that hit legacy URLs (plus the false positive rate) go through the full lookup process.
Sizing for 8.4M URLs
The Bloom filter sizing formula: for n elements and desired false positive rate p, optimal bit array size m = -(n * ln(p)) / (ln(2)^2).
For 8.4M URLs at a 0.1% false positive rate:
n = 8,412,847
p = 0.001 (0.1% false positive rate)

m = -(8,412,847 * ln(0.001)) / (ln(2)^2)
m = -(8,412,847 * -6.9078) / 0.4805
m = 58,127,403 / 0.4805
m ≈ 120,975,000 bits
m ≈ 14.38 MB

Optimal number of hash functions k = (m/n) * ln(2)
k = (120,975,000 / 8,412,847) * 0.6931
k ≈ 14.38 * 0.6931
k ≈ 10 hash functions
14.4MB for the entire Bloom filter. This fits comfortably in a Cloudflare Worker's memory budget (128MB limit, though Workers rarely use more than 10–20MB for typical logic). The filter is serialized as a base64 blob, stored in KV, loaded once per Worker invocation cold start, and cached in memory for subsequent requests in the same isolate.
Cloudflare Workers Architecture
KV Storage Patterns
Cloudflare KV is the backing store for the redirect table. But 8.4M KV keys at Cloudflare's pricing is expensive, and KV lookups add latency. The architecture that worked for us:
- Bloom filter in KV: single key, 14.4MB value, loaded at Worker cold start, cached in memory
- Redirect table in KV: chunked by URL hash prefix, 100K entries per chunk (84 chunks total)
- Hot redirects in a separate KV namespace: the top 50,000 redirects by traffic volume, loaded individually for sub-1ms lookup
The hot/cold split matters. In practice, 80% of redirect traffic goes to 0.6% of the redirect table. The top 50K redirects account for the vast majority of traffic hits. Those get individual KV entries for fast lookup. The remaining 8.36M redirects go into chunked lookup—slower, but they're rarely hit.
The Worker Code
// Cloudflare Worker: 8.4M redirect processing with Bloom filter
import { BloomFilter } from './bloom-filter.js'

// Module-level cache — persists across requests in the same isolate
let bloomFilter = null
let hotRedirects = null
let lastLoaded = 0
const CACHE_TTL_MS = 300_000 // 5 minutes

async function loadBloomFilter(env) {
  const data = await env.REDIRECTS_KV.get('bloom_filter', { type: 'arrayBuffer' })
  if (!data) throw new Error('Bloom filter not found in KV')
  return BloomFilter.fromBuffer(data, 10) // 10 hash functions
}

async function loadHotRedirects(env) {
  const data = await env.REDIRECTS_KV.get('hot_redirects', { type: 'json' })
  return new Map(Object.entries(data || {}))
}

async function lookupChunkedRedirect(env, url) {
  // Hash the URL to find the right chunk
  const hash = simpleHash(url)
  const chunkIndex = Math.floor((hash % 100) / (100 / 84)) // 84 chunks
  const chunkKey = chunk_${String(chunkIndex).padStart(3, '0')}

  const chunk = await env.REDIRECTS_KV.get(chunkKey, { type: 'json' })
  if (!chunk) return null

  return chunk[url] || null
}

function simpleHash(str) {
  let hash = 0
  for (let i = 0; i < str.length; i++) {
    hash = ((hash << 5) - hash) + str.charCodeAt(i)
    hash |= 0
  }
  return Math.abs(hash)
}

export default {
  async fetch(request, env, ctx) {
    const url = new URL(request.url)
    const pathname = url.pathname + url.search
    const now = Date.now()

    // Refresh caches if stale
    if (!bloomFilter || (now - lastLoaded) > CACHE_TTL_MS) {
      try {
        [bloomFilter, hotRedirects] = await Promise.all([
          loadBloomFilter(env),
          loadHotRedirects(env)
        ])
        lastLoaded = now
      } catch (e) {
        // If filter load fails, pass through to origin
        console.error('Bloom filter load failed:', e.message)
        return fetch(request)
      }
    }

    // Step 1: Bloom filter pre-screen
    // If definitely NOT a redirect, skip all lookup logic
    if (!bloomFilter.mightContain(pathname)) {
      return fetch(request)
    }

    // Step 2: Check hot redirect table (O(1) lookup)
    const hotTarget = hotRedirects.get(pathname)
    if (hotTarget) {
      return Response.redirect(
        new URL(hotTarget, url.origin).toString(),
        301
      )
    }

    // Step 3: Chunked KV lookup for cold redirects
    const coldTarget = await lookupChunkedRedirect(env, pathname)
    if (coldTarget) {
      return Response.redirect(
        new URL(coldTarget, url.origin).toString(),
        301
      )
    }

    // Bloom filter false positive — pass through
    return fetch(request)
  }
}
The three-tier lookup (Bloom → hot map → chunked KV) means:
- ~95% of non-redirect requests: 1 Bloom filter lookup, ~0.1ms
- ~80% of redirect requests: hot map lookup, ~0.2ms
- ~20% of redirect requests: chunked KV, ~3–5ms
- False positives (~0.1%): chunked KV miss, ~3–5ms
Weighted average across all traffic: under 1ms for the redirect logic layer. Total TTFB for redirected requests was 6–8ms in production, measured against the 340ms origin baseline.
The Fastly Compute@Edge Alternative
If you're running Fastly instead of Cloudflare, the architecture is similar but the implementation differs. Fastly Compute@Edge runs WebAssembly modules compiled from Rust, Go, or AssemblyScript. The Bloom filter approach works identically—you're still doing an in-memory pre-screen before hitting a backing data store.
Fastly's equivalent to Cloudflare KV is the Config Store for small key-value data and the Object Store (now called KV Store in Fastly's 2025 rebranding) for larger datasets. The chunked lookup pattern maps directly.
// Fastly Compute@Edge (AssemblyScript): redirect lookup sketch
import { KVStore, Request, Response } from "@fastly/as-compute"

// Bloom filter bytes loaded from KV Store at module initialization
let filterBytes: Uint8Array = new Uint8Array(0)

function mightBeRedirect(path: string, filter: Uint8Array): bool {
  // Simplified Bloom filter check — real implementation uses multiple hashes
  const hashes = computeHashes(path, 10)
  for (let i = 0; i < hashes.length; i++) {
    const byteIndex = (hashes[i] % (filter.length * 8)) >> 3
    const bitIndex = hashes[i] % 8
    if ((filter[byteIndex] & (1 << bitIndex)) === 0) {
      return false // Definitely not in set
    }
  }
  return true // Probably in set
}

export function main(req: Request): Response {
  const path = new URL(req.url).pathname

  // Pre-screen with Bloom filter
  if (filterBytes.length > 0 && !mightBeRedirect(path, filterBytes)) {
    return fetch(req, { backend: "origin" })
  }

  // Lookup in KV Store
  const store = new KVStore("redirect_table")
  const target = store.get(path)

  if (target !== null) {
    return new Response(null, {
      status: 301,
      headers: { "Location": target.text() }
    })
  }

  return fetch(req, { backend: "origin" })
}
Fastly's Rust SDK gives you better type safety and slightly faster WASM execution than AssemblyScript, but for teams already writing TypeScript-adjacent code, AssemblyScript is the lower-friction path to production.
Chain Collapse at Ingest Time
The redirect table I inherited had chains. Long ones. The worst I found was a 7-hop chain: URL A redirected to B, which redirected to C, which redirected to D, which redirected to E, which redirected to F, which redirected to the final destination G. Each hop was a separate database entry, added by a different team member over eight years.
For SEO, every additional hop in a redirect chain increases the probability that PageRank is lost in transit. Google's documentation doesn't give a specific number, but the practical guidance I've seen validated repeatedly is that chains longer than 3 hops start causing indexation problems. Chains of 7 are definitely losing equity.
For TTFB, chains at origin mean n database lookups and n round trips. At edge, they mean n Worker invocations—each of which processes the next hop—before the final 301 is issued. This is only marginally better.
Chain collapse at ingest time means flattening all chains to direct A → G mappings before loading into the edge table. The script for this:
#!/usr/bin/env python3
"""
Collapse redirect chains to single hops.
Input: CSV with source,destination columns
Output: CSV with all chains resolved to direct mappings
"""

import csv
import sys
from collections import defaultdict

def load_redirects(filepath):
    redirects = {}
    with open(filepath, 'r') as f:
        reader = csv.DictReader(f)
        for row in reader:
            src = row['source'].strip().lower()
            dst = row['destination'].strip()
            redirects[src] = dst
    return redirects

def resolve_chain(source, redirects, visited=None):
    if visited is None:
        visited = set()

    if source in visited:
        # Circular redirect detected — return None to flag for review
        print(f"CIRCULAR: {source}", file=sys.stderr)
        return None

    visited.add(source)
    destination = redirects.get(source)

    if destination is None:
        # source is the final destination
        return source

    # Normalize destination to check if it's also in the redirect table
    dest_key = destination.strip().lower()
    if dest_key in redirects:
        # This destination itself redirects — follow the chain
        return resolve_chain(dest_key, redirects, visited)

    return destination

def collapse_chains(redirects):
    collapsed = {}
    circular = []

    for source in redirects:
        final = resolve_chain(source, redirects)
        if final is None:
            circular.append(source)
        elif final.lower() != source:
            collapsed[source] = final

    return collapsed, circular

def main():
    if len(sys.argv) != 3:
        print("Usage: collapse_chains.py input.csv output.csv")
        sys.exit(1)

    redirects = load_redirects(sys.argv[1])
    print(f"Loaded {len(redirects):,} redirects", file=sys.stderr)

    collapsed, circular = collapse_chains(redirects)
    print(f"Collapsed to {len(collapsed):,} direct mappings", file=sys.stderr)
    print(f"Circular redirects found: {len(circular)}", file=sys.stderr)

    with open(sys.argv[2], 'w', newline='') as f:
        writer = csv.DictWriter(f, fieldnames=['source', 'destination'])
        writer.writeheader()
        for source, destination in collapsed.items():
            writer.writerow({'source': source, 'destination': destination})

if __name__ == '__main__':
    main()
Running this against the inherited redirect table found 847 circular redirects (a URL eventually redirecting back to itself through a chain of intermediaries) and collapsed 2.1M chained entries into direct mappings. The actual distinct URL count dropped from 8.4M entries to 6.3M unique source URLs with valid destinations.
Monitoring and Drift
The redirect table is not a fire-and-forget asset. URLs that were valid redirect destinations in January may be 404s by May if the destination platform restructures. When that happens, you've converted a redirect to a 301 → 404 chain—arguably worse than the original legacy URL, because it signals to Google that the destination no longer exists.
The monitoring stack we run:
- Weekly destination health check: sample 5% of redirect destinations, verify they return 200 or an expected redirect
- GSC coverage report integration: flag any destination URLs appearing in the "Not found (404)" report that are in our redirect target set
- Real-time alerting on 404 rate spikes from the edge: if the Worker is processing redirects to 404-returning destinations, Cloudflare's Analytics triggers an alert within 15 minutes
In the post-2025 GSC UI refresh, the coverage report moved from "Index Coverage" to "Indexing" → "Pages" with a slightly different filter interface. The underlying data is the same, but if you built any automations around the old URL structure for GSC API calls, they likely broke in the October 2025 refresh cycle. Worth checking your reporting pipelines if you haven't already.
SEO Implications of Edge Redirects
A concern I hear regularly: does Google treat edge-issued 301s differently from origin-issued 301s?
No. A 301 response header is a 301 response header. Google's crawler does not—as far as any published documentation or observable testing suggests—distinguish between a redirect issued by a Cloudflare Worker and one issued by Nginx at origin. The response code and Location header are what matter. The infrastructure layer is invisible to the crawler.
What does matter for SEO from edge redirect architecture:
Speed of propagation for new redirects. When you add a new redirect at origin, there's typically a deployment pipeline. At the edge, with the chunked KV approach, a new redirect is added to the KV store and propagates to all PoPs within 60 seconds. For time-sensitive redirects (press releases going live, product pages being replaced), this matters.
Crawl efficiency for redirect resolution. The faster Googlebot can resolve a redirect, the more redirect chains it can process in a single crawl budget allocation. An 8ms TTFB vs. a 340ms TTFB for redirected URLs means Google can crawl 42x more redirects per second of crawl budget. For a site with 8.4M redirects, this is the difference between complete redirect chain indexation within weeks vs. months.
Redirect consistency across geographic crawl points. Googlebot crawls from US-based IPs, but Google also crawls from other geographies for certain checks. An edge-based redirect table that's consistent across all PoPs—which KV replication ensures—means every crawl request gets the same redirect response regardless of which PoP processes it.
Two Things Most Engineers Get Wrong
1. 301s are not always the right status code for migrated URLs. The reflexive choice is 301—permanent redirect, signals "this URL moved permanently." But permanent redirects are cached aggressively by browsers. A user who visits a 301 redirect from their browser will have the redirect cached for the duration of the browser session, sometimes longer. If you later change the destination, that user won't see the update until cache clears.
For product pages that might move again (seasonal items, bundle pages), 302 is often the better operational choice even if it's theoretically less correct for SEO. The SEO difference between 301 and 302 is smaller than it used to be—Google's documentation has quietly softened the "302s don't pass PageRank" absolutism from the 2010s. A 302 that exists for more than a few weeks gets treated similarly to a 301 in practice.
I use 302 for any redirect destination I'm not confident will be stable for at least 12 months. This is the minority position among SEOs. I'm making it anyway.
2. The "temporary" redirect table that never gets cleaned up causes more long-term harm than keeping legacy URLs live. Every redirect is a server-side cost: a lookup, a response, a crawl budget hit. A redirect to a destination that no longer reflects the current site structure is actively misleading to users who follow the redirect and find something unexpected. The SEO community treats redirect hygiene as a one-time migration task. It isn't. It's ongoing maintenance, and the redirect tables that aren't maintained become technical debt faster than almost anything else in the stack.
The Mistake I Made
In the initial deployment of this system in January 2026, I configured the Bloom filter with a false positive rate of 1% instead of 0.1%. My reasoning: 1% is close enough, and the smaller filter size (about 10MB vs. 14.4MB) seemed worth the tradeoff.
What I didn't account for: at 8.4M entries and 1% false positive rate, roughly 84,000 non-redirect URLs would trigger false positives on every request. Most of these were high-traffic product pages. Every request to those pages went through the full chunked KV lookup, found nothing, and passed through to origin—adding 3–5ms to every request. For our highest-traffic pages, this was measurable in Core Web Vitals.
The fix was straightforward: rebuild the filter at 0.1% false positive rate. But it cost two days of work to diagnose, rebuild, and deploy. The lesson: for Bloom filters on high-traffic sites, false positive rate matters more than filter size. Spend the extra 4MB.
Closing
8.4M redirects at 8ms TTFB is achievable. The architecture is not particularly complex once you understand the data structure requirements. The Bloom filter pre-screen eliminates the lookup cost for the vast majority of requests. The hot/cold split optimizes for the power law distribution of redirect traffic. Chain collapse at ingest removes the latency multiplier of multi-hop chains.
What makes this hard is not the implementation—it's the operational discipline. Redirect tables grow in one direction without intervention. The monitoring stack has to catch destination drift before Google does. The deployment pipeline for table updates has to be faster than manual processes. And the organizational will to clean up circular redirects and invalid destinations has to be maintained over years, not just at migration time.
The edge compute infrastructure to do this well has been standard since 2024. The gap isn't tooling anymore. It's process.
See also: multilingual SEO without hreflang | post-acquisition site mergers | brand SERP defense
External references: [Cloudflare Workers KV documentation] | [Bloom Filters by Example]