The proxy layer between origin and crawler is the most underutilized surface in technical SEO. While most practitioners debate meta tags and internal link structure, a small cohort of senior engineers has quietly moved critical SEO logic—redirects, header injection, hreflang routing, bot differentiation—into Cloudflare Workers, executing at sub-millisecond latency across 300+ PoPs before a single byte leaves the origin. This article is about that cohort's playbook.
Edge SEO is not about caching static assets. It is about treating the CDN edge as a programmable SEO middleware layer: one that can rewrite responses, inject structured data, enforce canonical policy, and segment crawler traffic with zero origin coupling. When done correctly, it compresses the feedback loop between an SEO decision and its live deployment from days (CMS deploys, dev queues) to seconds.
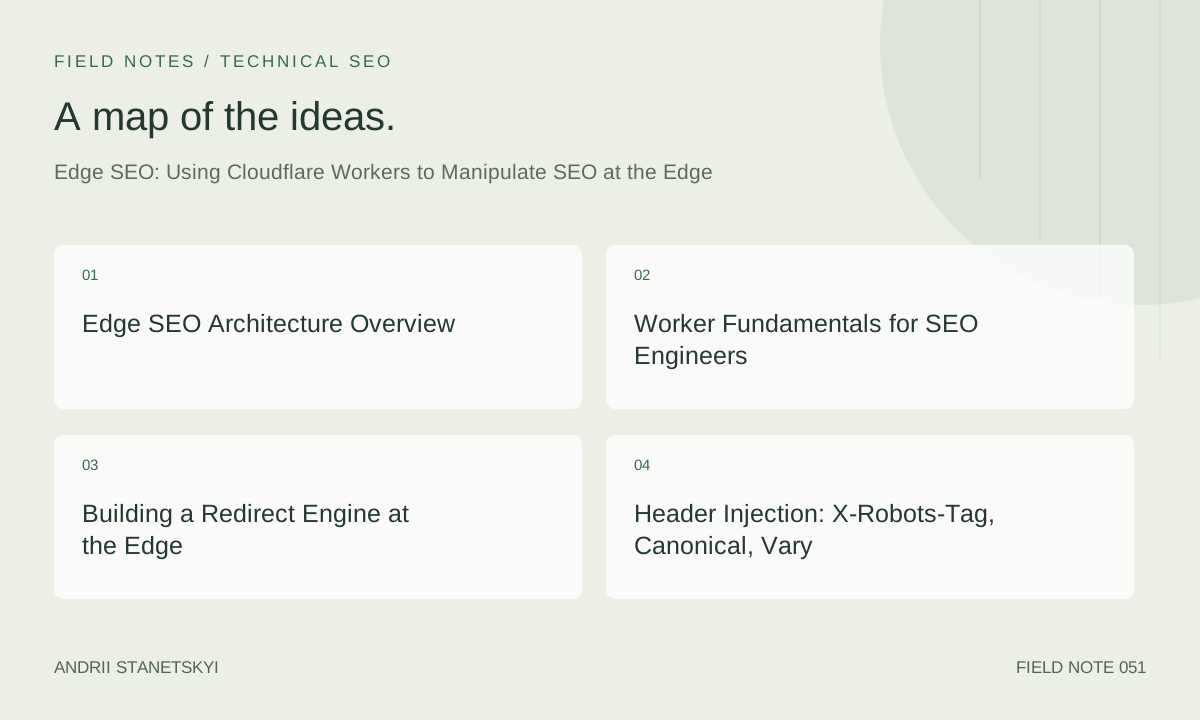
Edge SEO Architecture Overview
A Cloudflare Worker sits in the request/response lifecycle between the client (Googlebot included) and your origin. It intercepts every HTTP transaction and can mutate request headers, response headers, response body, and routing decisions. The execution environment is V8 isolates—not Node.js—which means no filesystem access, tight CPU limits (10ms CPU time on the free tier, 30ms on paid, 50ms with Unbound), and a Service Worker-style event model.
From an SEO architecture standpoint, the Worker gives you four distinct intervention points:
- Request mutation: Rewrite URLs before they hit origin, route to alternate origins based on UA string, inject synthetic headers Googlebot expects.
- Origin response buffering: Capture the full response body, parse it, modify it, return to crawler. Expensive—use sparingly.
- Response header mutation: Add, remove, or overwrite any response header. This is where X-Robots-Tag, canonical enforcement, and Vary manipulation live.
- Synthetic responses: Return a complete HTTP response without touching origin at all. Ideal for redirect chains, 410 Gone enforcement, and canonical 301s.
The decision table below governs when each intervention point is appropriate:
| SEO Problem | Intervention Point | Origin Hit? | CPU Budget |
|---|---|---|---|
| 301/302 redirect | Synthetic response | No | <1ms |
| 410 Gone (deleted pages) | Synthetic response | No | <1ms |
| X-Robots-Tag injection | Response header mutation | Yes | <1ms |
| Canonical header injection | Response header mutation | Yes | <1ms |
| Hreflang routing | Request mutation + synthetic | Conditional | 2–5ms |
| JSON-LD injection | Response body mutation (HTMLRewriter) | Yes | 5–15ms |
| Crawler segmentation | Request mutation | Conditional | <2ms |
Worker Fundamentals for SEO Engineers
Cloudflare Workers use the FetchEvent model. Every incoming request triggers your addEventListener('fetch', handler). You get a Request object and must return a Response. The entire SEO manipulation surface lives in this lifecycle.
// Minimal Worker scaffold for SEO middleware
addEventListener('fetch', event => {
  event.respondWith(handleRequest(event.request));
});

async function handleRequest(request) {
  const url = new URL(request.url);
  const ua = request.headers.get('User-Agent') || '';

  // Googlebot detection — use verified IP ranges in production
  const isGooglebot = /Googlebot/i.test(ua);
  const isBingbot = /bingbot/i.test(ua);
  const isCrawler = isGooglebot || isBingbot || /Baiduspider|YandexBot/i.test(ua);

  // Check redirect table first — zero origin cost
  const redirect = getRedirect(url.pathname);
  if (redirect) {
    return Response.redirect(redirect.destination, redirect.statusCode);
  }

  // Fetch from origin
  const originResponse = await fetch(request);

  // Clone response to modify headers (Response is immutable)
  const newHeaders = new Headers(originResponse.headers);

  // Canonical enforcement
  const canonicalUrl = buildCanonical(url);
  newHeaders.set('Link', <${canonicalUrl}>; rel="canonical");

  // Crawler-specific header injection
  if (isCrawler) {
    newHeaders.set('X-Robots-Tag', getXRobotsTag(url.pathname));
  }

  return new Response(originResponse.body, {
    status: originResponse.status,
    headers: newHeaders
  });
}
The critical constraint: Response.body is a ReadableStream. If you need to modify the body (inject JSON-LD, fix canonical tags), you must either buffer the entire stream (memory-intensive) or use HTMLRewriter—Cloudflare's streaming HTML parser that processes the response as a pipeline, never fully materializing the DOM in memory.
Building a Redirect Engine at the Edge
A KV-backed redirect engine at the edge eliminates the origin for every redirect hit. Cloudflare KV is eventually consistent with ~60ms read latency on cache miss, but with a local cache (via cacheTime) effectively zero for hot entries.
The architecture: store redirect rules as JSON in KV, keyed by normalized path. On each request, look up the path, return synthetic 301/302/410 if found. For sites with 50k+ redirect rules (post-migration scenarios), partition by path prefix to avoid single-key bloat.
// KV-backed redirect engine
// KV namespace: SEO_REDIRECTS, bound in wrangler.toml

const CACHE_TTL = 300; // 5 minutes local cache

async function resolveRedirect(pathname) {
  // Normalize: strip trailing slash, lowercase
  const normalized = pathname.replace(/\/$/, '').toLowerCase() || '/';

  // Check KV with local caching
  const entry = await SEO_REDIRECTS.get(normalized, {
    type: 'json',
    cacheTtl: CACHE_TTL
  });

  return entry; // null if no redirect exists
}

// Redirect rule schema in KV:
// Key: "/old-path"
// Value: {"to": "/new-path", "code": 301, "note": "Q3 2025 migration"}

async function handleRedirects(request) {
  const url = new URL(request.url);
  const rule = await resolveRedirect(url.pathname);

  if (!rule) return null;

  if (rule.code === 410) {
    return new Response('Gone', {
      status: 410,
      headers: { 'X-Redirect-Rule': 'edge-gone' }
    });
  }

  // Preserve query string unless rule specifies strip
  const destination = rule.stripQuery
    ? rule.to
    : rule.to + (url.search || '');

  return Response.redirect(
    https://${url.hostname}${destination},
    rule.code
  );
}

// Bulk load redirects via Cloudflare API (wrangler KV bulk)
// wrangler kv:bulk put --namespace-id= redirects.json
// redirects.json format: [{"key": "/old", "value": "{\"to\":\"/new\",\"code\":301}"}]
For sites migrating from one domain to another, combine path-based KV lookup with a domain-level rewrite. The Worker intercepts the old domain (configured as a Cloudflare zone), looks up the path, and returns a 301 to the new domain—all without touching origin infrastructure, which may be decommissioned.
Header Injection: X-Robots-Tag, Canonical, Vary
HTTP headers for SEO are underused relative to their power. The X-Robots-Tag header is semantically equivalent to the <meta name="robots"> tag but applies to any content type—PDFs, images, JSON feeds—and cannot be accidentally stripped by a CMS. Injecting it at the edge means it is always present regardless of origin behavior.
// Granular X-Robots-Tag logic at the edge
function getXRobotsTag(pathname) {
  // Parameter-polluted URLs — noindex at edge, no CMS involvement
  if (/[?&](ref|utm_|session|token|debug)/.test(pathname)) {
    return 'noindex, nofollow';
  }

  // Faceted navigation patterns
  if (/\/(filter|sort|page)\//.test(pathname)) {
    return 'noindex, follow';
  }

  // Print versions
  if (/\/print\/|\.print$/.test(pathname)) {
    return 'noindex, nofollow';
  }

  // Staging path leaked to prod (shouldn't happen, but...)
  if (/^\/(staging|preview|draft)\//.test(pathname)) {
    return 'noindex, nofollow';
  }

  return 'index, follow';
}

// Canonical Link header — useful when origin sets wrong canonical in HTML
// Edge canonical header takes precedence in most crawler implementations
function enforceCanonical(url) {
  let canonical = https://${url.hostname}${url.pathname};

  // Strip known dirty parameters
  const dirtyParams = ['utm_source','utm_medium','utm_campaign',
                       'gclid','fbclid','ref','mc_eid'];
  const params = new URLSearchParams(url.search);
  dirtyParams.forEach(p => params.delete(p));

  const cleanSearch = params.toString();
  if (cleanSearch) canonical += ?${cleanSearch};

  return canonical;
}
The Vary header is the most dangerous header in the SEO toolkit. Setting Vary: User-Agent on a CDN instructs it to maintain separate cache entries per User-Agent string—catastrophic for cache efficiency. The correct approach for crawler-differentiated content is to vary on a normalized bot/human binary, not the raw UA string.
// Safe Vary header management for crawler-differentiated responses
function setVaryHeader(headers, isCrawler) {
  if (isCrawler) {
    // Signal to downstream caches that content varies by crawler status
    // Use a custom header to avoid Vary: User-Agent explosion
    headers.set('Vary', 'Accept-Encoding, X-Is-Crawler');
    headers.set('X-Is-Crawler', '1');
  } else {
    headers.set('Vary', 'Accept-Encoding');
    headers.set('X-Is-Crawler', '0');
  }

  // Ensure Cloudflare itself caches correctly
  headers.set('Cache-Control', 'public, max-age=3600, s-maxage=86400');
}
Hreflang Routing at the Edge
Hreflang at scale is a combinatorial problem. A site with 40 locales and 200k pages generates 8 million hreflang annotations. Maintaining these in XML sitemaps or HTML head tags requires heavy origin-side computation. Moving hreflang logic to the edge—where it is computed on demand from a KV-stored locale map—eliminates the build-time dependency.
// Edge hreflang injection via HTMLRewriter
// Locale map stored in KV: pathname -> { "en-US": "/path", "de": "/de/path", ... }

class HreflangInjector {
  constructor(localeMap, currentUrl) {
    this.localeMap = localeMap;
    this.currentUrl = currentUrl;
    this.injected = false;
  }

  element(element) {
    // Inject after opening
Crawler Segmentation and Differential Responses
Legitimate crawler segmentation—serving identical content but with different response timings, headers, or instrumentation—is distinct from cloaking. The line is drawn at content: if Googlebot sees different text than users, it is cloaking. If Googlebot sees the same text but different headers, timing, or infrastructure routing, it is operational SEO.
Verified bot detection requires IP range validation. Cloudflare Workers can access the connecting IP via request.headers.get('CF-Connecting-IP'). Cross-reference against Google's published Googlebot IP ranges stored in KV, updated via a scheduled Cron Worker.
// Verified Googlebot detection
// IP ranges fetched from https://developers.google.com/search/apis/ipranges/googlebot.json
// Stored in KV as: GOOGLEBOT_RANGES -> [{prefix: "66.249.64.0/19"}, ...]

function ipToLong(ip) {
  return ip.split('.').reduce((acc, octet) => (acc << 8) + parseInt(octet), 0) >>> 0;
}

function cidrContains(cidr, ip) {
  const [network, bits] = cidr.split('/');
  const mask = bits ? ~((1 << (32 - parseInt(bits))) - 1) >>> 0 : 0xFFFFFFFF;
  return (ipToLong(network) & mask) === (ipToLong(ip) & mask);
}

async function isVerifiedGooglebot(request) {
  const ua = request.headers.get('User-Agent') || '';
  if (!/Googlebot/i.test(ua)) return false;

  const clientIp = request.headers.get('CF-Connecting-IP');
  if (!clientIp) return false;

  const ranges = await GOOGLEBOT_RANGES.get('ranges', { type: 'json', cacheTtl: 3600 });
  if (!ranges) return false;

  return ranges.some(r => cidrContains(r.prefix, clientIp));
}

// Cron Worker to refresh IP ranges daily
// wrangler.toml: [triggers] crons = ["0 6 * * *"]
async function refreshGooglebotRanges(event) {
  const resp = await fetch(
    'https://developers.google.com/search/apis/ipranges/googlebot.json'
  );
  const data = await resp.json();
  await GOOGLEBOT_RANGES.put('ranges', JSON.stringify(data.prefixes));
}
Injecting JSON-LD Structured Data at the Edge
CMS platforms often cannot dynamically generate JSON-LD for complex entity types—SpeakableSpecification, ClaimReview, SpecialAnnouncement—without custom development. Edge injection via HTMLRewriter allows a separate structured data layer, maintained independently of the CMS, injected into every response without origin changes.
// JSON-LD injection via HTMLRewriter
// Schema rules stored in KV, keyed by path pattern

class JsonLdInjector {
  constructor(schema) {
    this.schema = schema;
  }

  element(element) {
    if (element.tagName === 'head') {
      const scriptTag = ``;
      element.append(scriptTag, { html: true });
    }
  }
}

async function injectStructuredData(response, url, pageMetadata) {
  // Build schema from edge-side metadata + KV template
  const templateKey = getSchemaTemplate(url.pathname);
  const template = await SCHEMA_TEMPLATES.get(templateKey, { type: 'json' });

  if (!template) return response;

  // Merge dynamic values from response headers (set by origin)
  const schema = {
    ...template,
    "@context": "https://schema.org",
    "url": url.toString(),
    "dateModified": response.headers.get('Last-Modified') || new Date().toISOString(),
    "name": pageMetadata.title
  };

  return new HTMLRewriter()
    .on('head', new JsonLdInjector(schema))
    .transform(response);
}

function getSchemaTemplate(pathname) {
  if (/^\/blog\//.test(pathname)) return 'article';
  if (/^\/products\//.test(pathname)) return 'product';
  if (/^\/authors\//.test(pathname)) return 'person';
  if (pathname === '/') return 'website';
  return 'webpage';
}
Performance Implications and Cache Poisoning Risks
Every Worker adds latency to the request path. The distribution is roughly: KV read (cache hit) ~0ms, KV read (cache miss) ~50-80ms, HTMLRewriter transform ~5-20ms depending on document size, fetch to origin ~varies. For large-scale deployments, budget Workers latency and instrument it.
// Worker performance instrumentation
addEventListener('fetch', event => {
  event.respondWith(handleWithTiming(event.request));
});

async function handleWithTiming(request) {
  const start = Date.now();
  const timings = {};

  // Time KV lookup
  const kvStart = Date.now();
  const redirect = await resolveRedirect(new URL(request.url).pathname);
  timings.kv = Date.now() - kvStart;

  if (redirect) {
    return Response.redirect(redirect.destination, redirect.code);
  }

  // Time origin fetch
  const originStart = Date.now();
  const response = await fetch(request);
  timings.origin = Date.now() - originStart;

  // Add timing headers for Cloudflare Analytics
  const headers = new Headers(response.headers);
  headers.set('Server-Timing',
    kv;dur=${timings.kv}, origin;dur=${timings.origin},  +
    total;dur=${Date.now() - start}
  );

  return new Response(response.body, { status: response.status, headers });
}
Cache poisoning risk: if your Worker injects different content based on request headers (UA, Accept-Language), and Cloudflare's cache does not understand your Vary strategy, cached responses can serve wrong content to subsequent requesters. Always set cf.cacheKey explicitly when serving differentiated content:
// Prevent cache poisoning with explicit cache keys
async function fetchWithCacheKey(request, isCrawler) {
  const url = new URL(request.url);

  // Create modified request with explicit cache key
  const cacheKey = new Request(
    ${url.origin}${url.pathname}${url.search}?__crawler=${isCrawler ? '1' : '0'},
    request
  );

  const cache = caches.default;
  let response = await cache.match(cacheKey);

  if (!response) {
    response = await fetch(request);
    // Clone before caching (body can only be consumed once)
    await cache.put(cacheKey, response.clone());
  }

  return response;
}
One architectural principle that prevents most cache poisoning issues: use the Worker for header mutation and routing, but never for body content differentiation between bots and users. Keep body content identical; only headers and routing should differ. This aligns with Google's guidelines and eliminates the cache poisoning vector simultaneously. See also: canonical enforcement strategies and international SEO architecture.
For monitoring edge SEO behavior, pipe Worker logs to Cloudflare Logpush → BigQuery. Query the structured logs to detect anomalies: unexpected 410s, redirect loops, hreflang injection failures. The BigQuery GSC analysis article covers this integration in depth.
FAQ
Does Googlebot execute Cloudflare Workers?
Yes. Googlebot makes standard HTTP requests through Cloudflare's network. Workers execute on every request regardless of client identity, so Googlebot receives the Worker-processed response. This is why edge SEO is powerful: there is no JavaScript rendering dependency. The response Googlebot receives is the final Worker output, not origin HTML plus client-side hydration.
Is serving different headers to Googlebot vs. users cloaking?
No, provided the response body is identical. Google's Webmaster Guidelines define cloaking as serving different content or URLs to humans and crawlers. Headers—X-Robots-Tag, Link canonical, hreflang—are metadata about the content, not the content itself. Differential header injection is standard technical SEO practice. Body content differentiation is cloaking.
What is the CPU time limit and how do I stay within it?
The Bundled Usage model gives 10ms CPU time per request. Unbound (Workers Paid) gives 30ms with 50ms burst. HTMLRewriter is streaming and efficient. The main CPU consumers are: JSON parsing of large KV values, complex regex on long strings, and cryptographic operations. Profile with Date.now() instrumentation and push expensive operations to Durable Objects if needed.
How do I handle redirect loops at the edge?
Validate your redirect rules for cycles before loading to KV. Implement a loop detection header: on each redirect synthetic response, check for X-Redirect-Count in the request. If it exceeds 3, return the origin response directly and log the loop. Workers cannot follow their own redirects (they return 3xx to the client), so redirect chains require multiple client round-trips anyway—detect cycles client-side too.
Can Workers inject hreflang for sites with 500k+ pages?
Yes, with proper KV partitioning. Structure your KV keys as {locale-cluster}:{path-hash} and look up only the cluster relevant to the current request's locale prefix. For 500k pages × 40 locales, store the locale map per canonical path (not per locale URL), so you have 500k KV entries each containing a 40-locale map. KV supports values up to 25MB; a 40-locale map is typically under 2KB.
Should I use Workers or origin middleware for SEO logic?
Redirect resolution, 410 enforcement, and header injection: Workers win on latency, deployment speed, and origin independence. Complex business logic requiring database lookups, authentication state, or real-time inventory: keep at origin. The edge is stateless except for KV and Durable Objects; design accordingly. For SEO logic that changes frequently (campaign redirects, seasonal noindex), the edge deployment speed advantage is decisive.
How do I test edge SEO changes before deploying to production?
Cloudflare Workers support preview deployments via wrangler dev --remote, which runs the Worker against production KV namespaces but on a preview URL. Use wrangler dev --local for pure local testing with mocked KV. For production validation, implement a ?edgeseo-debug=1 parameter gate that returns detailed header inspection without affecting crawler responses. Route Googlebot test crawls via the Search Console URL Inspection tool against the preview URL.
Key Takeaways
- Cloudflare Workers intercept every HTTP transaction including Googlebot, making them the fastest deployment surface for SEO header and routing changes.
- KV-backed redirect engines eliminate origin hits for redirect resolution; structure rules as normalized path → destination JSON with status code and metadata.
- HTMLRewriter enables streaming JSON-LD and hreflang injection without buffering full response bodies, keeping latency acceptable.
- Vary header mismanagement causes cache poisoning; use explicit cache keys (
cf.cacheKey) when serving differentiated responses. - Verified Googlebot detection requires IP range validation against Google's published CIDR list, not UA string matching alone.
- Body content must remain identical between crawler and user responses; only headers and routing may differ without crossing into cloaking.
- Instrument Workers with
Server-Timingheaders and Logpush to BigQuery for production SEO observability.
Conclusion
Edge SEO via Cloudflare Workers is not a replacement for foundational technical SEO—it is an amplifier. It collapses the deployment lag that kills SEO iteration velocity, removes origin coupling from critical SEO infrastructure, and provides a programmable layer that CMS platforms fundamentally cannot offer. The practitioners who have internalized this architecture are operating at a different cadence: redirect migrations that used to take sprint cycles now deploy in minutes; hreflang at 500k-page scale without sitemap file bloat; structured data injection without waiting on engineering queues. The edge is the SEO engineer's territory. Learn how to combine this with BigQuery-based crawl monitoring for a complete observability loop.